
 Contact
 How to shop

Delivery
Shopping guide
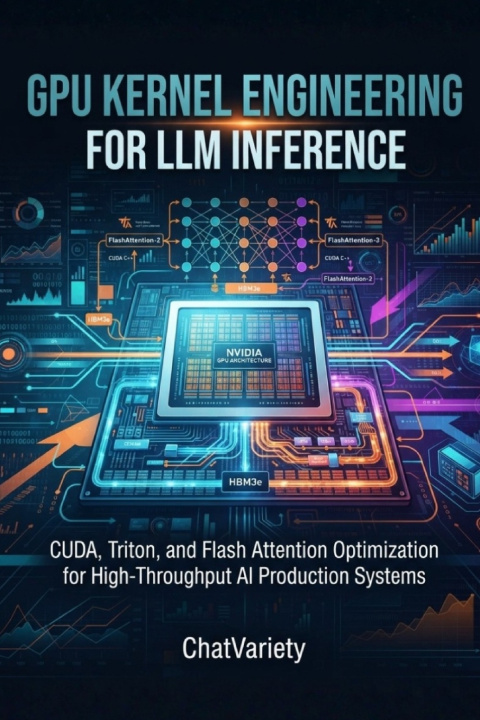
GPU Kernel Engineering for LLM Inference
CUDA, Triton, and Flash Attention Optimization for High-Throughput AI Production Systems
 English
 27 b
Up to 30 days for returns
You might also be interested in


 /
 Paperback
 30 757
Ft

Master GPU Kernel Engineering for Production LLM Inference
In the high-stakes world of AI production, the bottleneck isn't model architecture-it's execution efficiency. GPU Kernel Engineering for LLM Inference is the definitive engineering guide designed to close the gap between framework-level PyTorch code and hardware-optimal hardware performance.
Written specifically for machine learning engineers, systems software developers, and performance engineers, this practical manual provides deep, production-ready blueprints for building high-throughput AI serving infrastructure. You will move past theoretical concepts and dive straight into raw hardware-level optimizations that top AI teams use to slash latency and reduce infrastructure costs.
What You Will Master:- Custom CUDA Kernels: Write and optimize high-performance CUDA C++ kernels tailored specifically for modern Transformer workloads.
- Flash Attention 2 & 3: Implement advanced IO-aware attention algorithms with Hopper-specific asynchronous memory and Tensor Core operations.
- Triton Development: Build optimized fusion kernels for layer normalization, activation functions, and positional encodings using Python-level Triton.
- Quantization & GEMM: Develop high-throughput INT8, INT4, and weight-only quantized GEMM kernels for optimized memory footprints.
- PagedAttention & KV-Cache: Design vLLM-style virtual memory management kernels to eliminate memory fragmentation.
- Multi-GPU Scaling: Coordinate tensor-parallel all-reduce operations with custom NCCL collectives to scale seamlessly across cluster nodes.
- Nsight Profiling: Locate hardware bottlenecks using Nsight Systems and Nsight Compute.
Stop relying on out-of-the-box configurations. Equip yourself with the systems engineering skills required to build the next generation of high-speed, cost-efficient AI infrastructure. Learn to build kernels that run at the absolute physical limits of NVIDIA silicon.


About the book
English

Give this book today
It's easy
1 Add to cart and choose Deliver as present at the checkout 2 We'll send you a voucher 3 The book will arrive at the recipient's addressHi! I'm Libroamiko, your book advisor.
How can I help you?